SNP QC based on nature protocol
确定研究内容→QC样本→QC缺数据→QC分组→QC基础性质
-
1.获取数据
-
这里使用千人基因组的示例数据(约为20Mb,基于python hail包),10879 SNPs and 284 individuals. 关注发色研究
-
可使用hail.utils.get_1kg快速获得
-
vcftools --vcf 1kg.vcf --plink --out raw-GWA-data,并用脚本将1kg_annotations.txt中的表型信息置入ped文件中 -
制作bed文件(可以加速后面计算)
plink --file raw-GWA-data --make-bed --out raw-GWA-data之后就可以用-bfile了,且记录会在raw-GWA-data.log中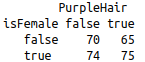 ------ (Candidate gene studies) 先做这两步骤,若是GWS研究这两步骤到后面
2.检查Case control的组间缺失差异
-
plink --bfile raw-GWA-data --test-missing --out clean-inds-GWA-data -
perl run-diffmiss-qc.pl clean-inds-GWA-data -
产生fail-diffmiss-qc.txt文件,由于下载数据样本较少,P <0.00001,此处 run-diffmiss-qc.pl 中阈值改为0.01 3.基础质控
-
plink --file raw-PPARG-data --exclude fail-diffmiss-qc.txt –mind 0.1 –-maf 0.01 --geno 0.05 --hwe 0.00001 --recode --out clean-PPARG-data----- (Candidate gene studies) -
4 . Identification of individuals with discordant sex information
-
plink --bfile raw-GWA-data --check-sex --out raw-GWA-data -
grep PROBLEM raw-GWA-data.sexcheck > raw-GWA-data.sexprobs -
手动检查挑一下fail-sexcheck-qc.txt 用于后续的
--remove fail-sexcheck-qc.txt,这里发现原始数据没有Y染色体数据,因此所错的都是男性判断错误,先搁下不管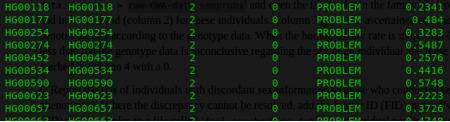
-
5 . Identification of individuals with elevated missing data rates or outlying heterozygosity rate
-
plink --bfile raw-GWA-data --missing --out raw-GWA-data -
plink --bfile raw-GWA-data --het --out raw-GWA-data -
raw-GWA-data.imiss 样本缺失, raw-GWA-data.lmiss 基因型缺失 , raw-GWA-data.het 杂合率
-
R CMD BATCH QC_imiss_het.R 观察缺失的质量,一般 exclude all individuals with a genotype failure rate ≥ 0.03 and/or heterozygosity rate ± 3 standard deviations from the mean. 生成 fail-imisshet-qc.txt,要删除33个样本
-
6 . Identification of duplicated or related individuals
-
plink --file raw-GWA-data --exclude high-LD-regions.txt --range --indep-pairwise 50 5 0.2 --out raw-GWA-data(未获得high-LD-regions.txt,实际使用plink --file raw-GWA-data --indep-pairwise 50 5 0.2 --out raw-GWA-data) -
plink --bfile raw-GWA-data --extract raw-GWA-data.prune.in --genome --out raw-GWA-data -
perl run-IBD-QC.pl raw-GWA-data产生fail-IBD-QC.txt,要删除一个样本 -
7*.Identification of individuals of divergent ancestry(可选步)
-
bash Build_HapMapb37_ref把这些民族信息先下下来 (太大,这步跳过…) -
plink --bfile raw-GWA-data --extract hapmap3r2_CEU.CHB.JPT.YRI.no-at-cg-snps.txt --make-bed --out raw-GWA-data.hapmap-snps -
plink --bfile raw-GWA-data -hapmap-snps --bmerge hapmap3r2_CEU.CHB.JPT.YRI.founders.no-at-cg-snps.bed hapmap3r2_CEU.CHB.JPT.YRI.founders.no-at-cg-snps.bim hapmap3r2_CEU.CHB.JPT.YRI.founders.no-at-cg-snps.fam --extract raw-GWA-data.prune.in --make-bed --out raw-GWA-data.hapmap3r2.pruned合并数据,这步应该很多坑… -
cp raw-GWA-data.hapmap3r2.pruned.bim raw-GWA-data.hapmap3r2.pruned.pedsnp -
cp raw-GWA-data.hapmap3r2.pruned.fam raw-GWA-data.hapmap3r2.pruned.pedind -
perl smartpca.perl -i raw-GWA-data.hapmap3r2.pruned.bed -a raw-GWA-data.hapmap3r2.pruned.pedsnp-b raw-GWA-data.hapmap3r2.pruned.pedind -o raw-GWA-data.hapmap3r2.pruned.pca -p raw-GWA-data.hapmap3r2.pruned.plot -e raw-GWA-data.hapmap3r2.pruned.eval -l raw-GWA-data.hapmap3r2.pruned.log -k 2 -t 2 -w pca-populations.txt使用主成分分析,用前两个PC来判断亲缘关系 -
exclude all individuals with a 2nd principal component score less than 0.072. Write the FID and IID of these individuals to a file called ‘fail-ancestry-QC.txt’.
-
8 . 删除之前不合格的样本
-
cat fail-* | sort -k1 | uniq > fail-qc-inds.txt共34个 -
plink —bfile raw-GWA-data —remove fail-qc-inds.txt —make-bed —out clean-inds-GWA-data 剩了250个样本
-
Total genotyping rate is 0.986696. → Total genotyping rate in remaining samples is 0.992243.
-
9 .Identify all markers with an excessive missing data rate
-
plink --bfile clean-inds-GWA-data --missing --out clean-inds-GWA-data基因型的缺失情况clean-inds-GWA-data.lmiss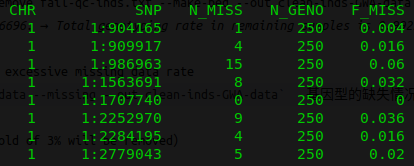
-
Rscript lmiss-hist.R -
生成fail-snpmiss-qc.txt (threshold of 3% will be removed)
-
10.检查Case control的组间缺失差异
-
plink --bfile raw-GWA-data --test-missing --out clean-inds-GWA-data -
perl run-diffmiss-qc.pl clean-inds-GWA-data -
产生fail-diffmiss-qc.txt文件,由于下载数据样本较少,P <0.00001,此处 run-diffmiss-qc.pl 中阈值改为0.01
-
11.基础质控
-
cat fail-snpmiss-qc.txt >> fail-diffmiss-qc.txt | uniq -
plink --bfile clean-inds-GWA-data --exclude fail-diffmiss-qc.txt --maf 0.01 --geno 0.05 --hwe 0.00001 --make-bed --out clean-GWA-data -
8561 variants and 250 people pass filters and QC.
-
clean-GWA-data 就是最终结果
-
可以看到QC前后样本和基因型的过滤效果
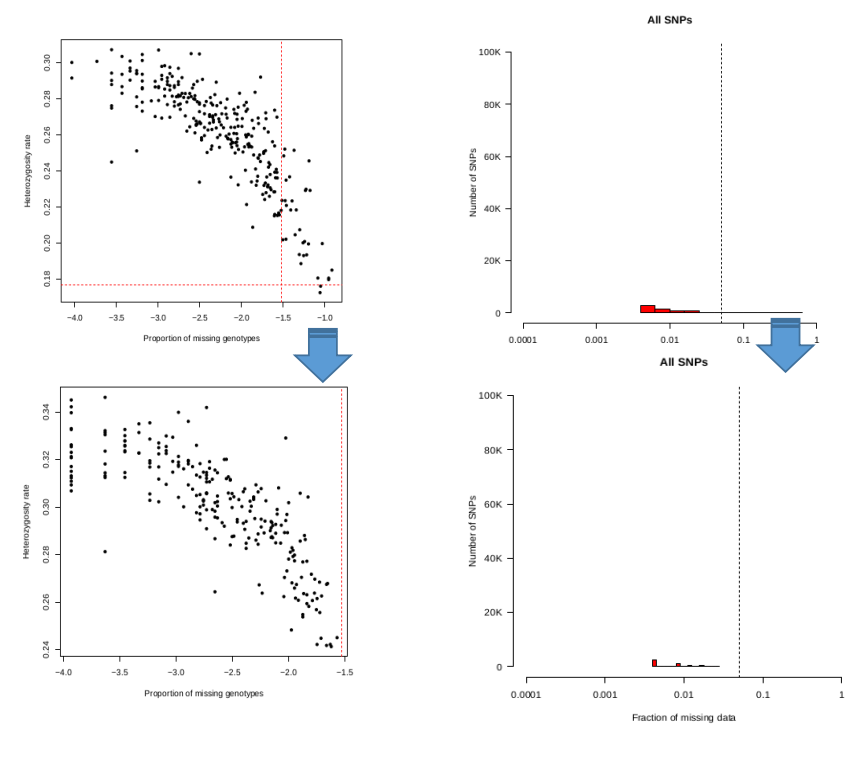
-
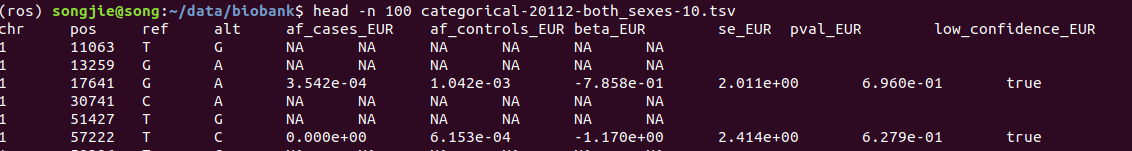
Data-Field: 50 The UK Biobank project is a prospective cohort study with deep genetic and phenotypic data collected on approximately 500,000 individuals from across the United Kingdom, aged between 40 and 69 at recruitment
-
基因型信息(芯片数据)
-
Hail适用的MatrixTable(.mt)格式(12.78 T)
-
SNP信息
-
描述文件 https://pan.ukbb.broadinstitute.org/docs/per-phenotype-files https://pan-ukb-us-east-1.s3.amazonaws.com/sumstats_release/full_variant_qc_metrics.txt.bgz 里面会有位置,等位基因型,人口数,临近基因的等信息
-
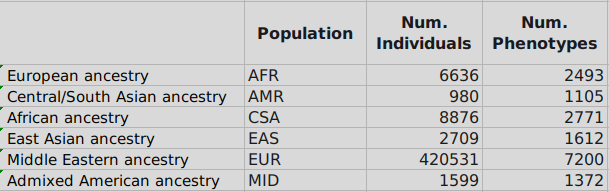
表型信息(7221个,基于50w人数据) https://pan.ukbb.broadinstitute.org/docs/background
-
数据概要表 https://docs.google.com/spreadsheets/d/1AeeADtT0U1AukliiNyiVzVRdLYPkTbruQSk38DeutU8/edit?usp=sharing
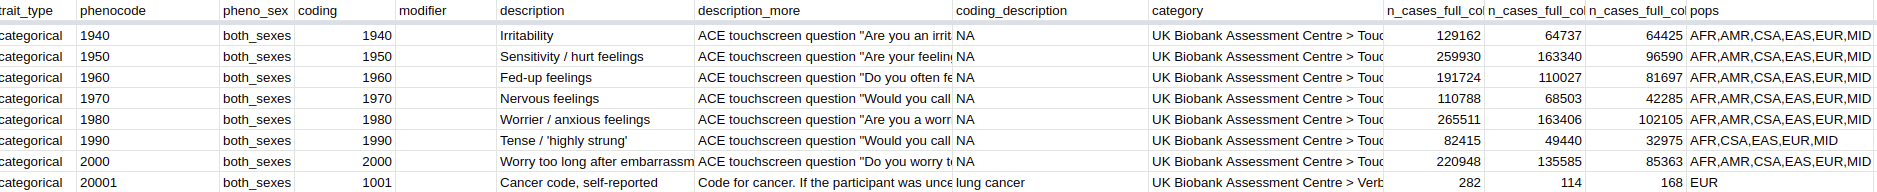 类型分布:

-
实际表型表: